
A company I had known for years asked me to audit its codebase and development team. I knew the product from the outside, knew people who worked there, and had once done a small contract job for them. This time the question was much bigger: why was development moving so slowly, and what could they do about it?
I gave myself a week to investigate and write a report. I had never audited a project quite this complicated. Naturally, I was curious.
First, find out where I landed
The business had little technical expertise of its own. Development looked like a black box: money and requests went in; eventually, something came out. Why one change took a week and another took months was harder to see.
So this was never going to be a code review alone. I needed to look at the architecture, the delivery process, the team, and the reasons changes had become expensive. I got access to the code and migrations, the task tracker, documentation, staging and production environments, the database structure, work chats, and the people building the product. I also joined team meetings.
There were healthy signs. Code review existed. Parts of the backend had tests. Weekly meetings sounded constructive. At the same time, many tasks had almost no written description or deadline, and important context traveled by voice. It was not a story in which everything was broken.
Then I opened the code
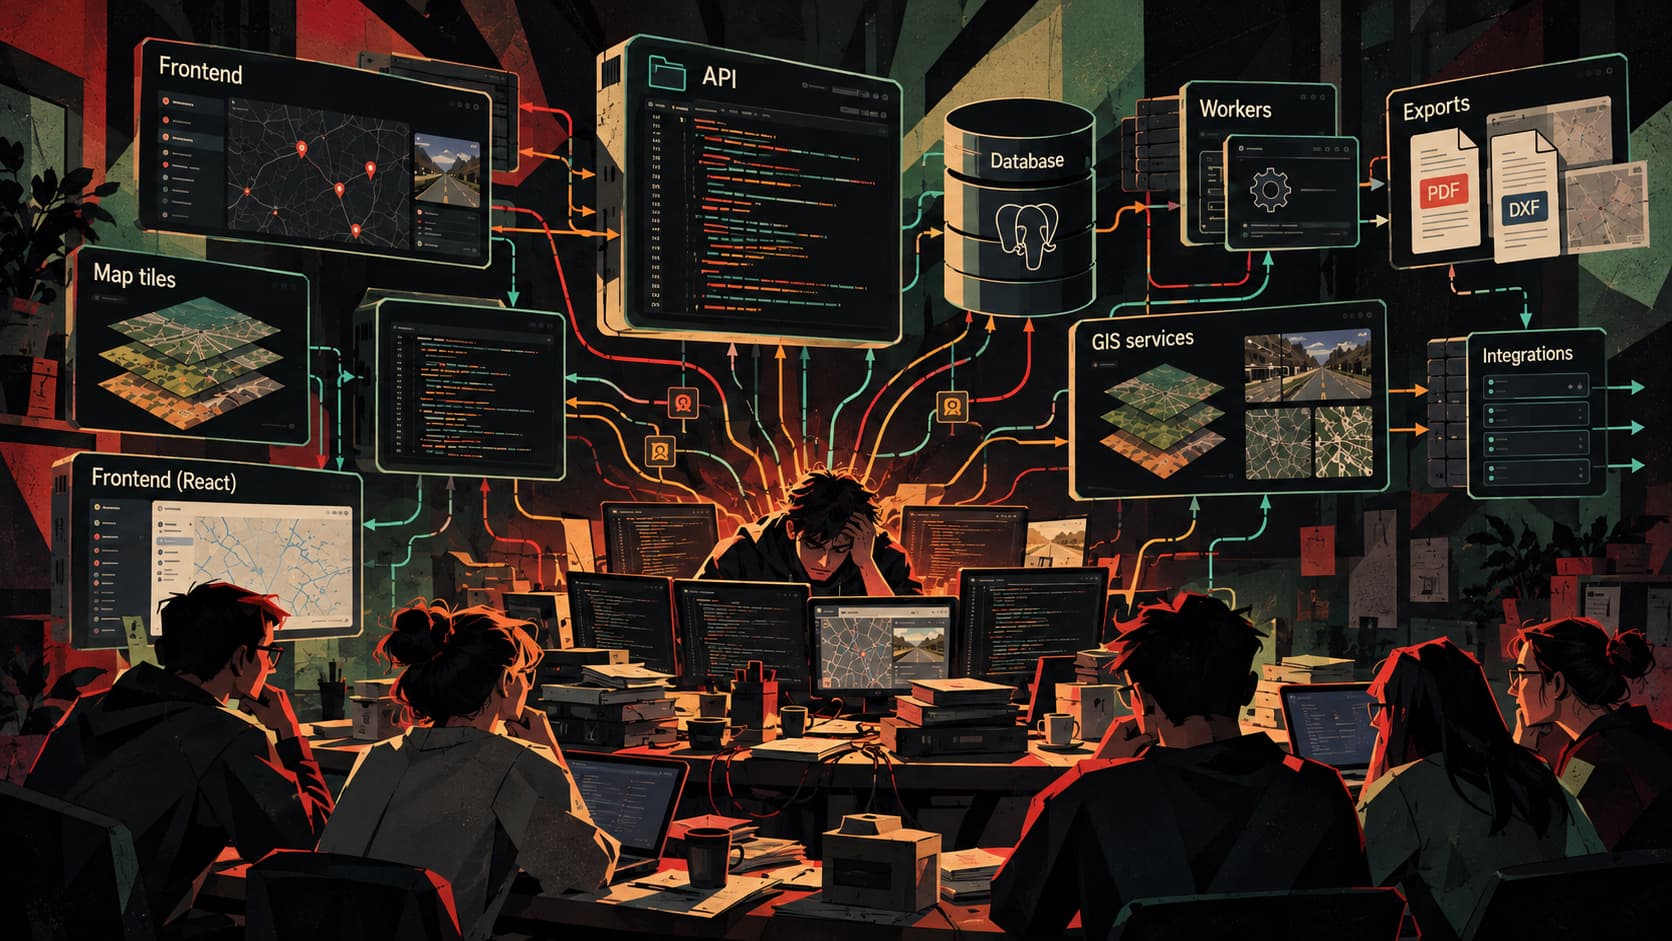
The product was a substantial GIS system: Python, PostGIS, React, older HTML and JavaScript applications, APIs, workers, a tile server, customer integrations, geodata processing, maps, panoramas, and several export pipelines. Its core was a complex editor for geometry and data on maps and panoramic images. Supporting services processed data, generated documents, and prepared deliverables for customers.
Different parts had arrived at different points in the product’s ten-year life. Before long I found a central Python API module that ran to 6,800 lines. Database calls and requests to other services passed through it. It was not the only enormous module.
Finding a file that size is easy. Understanding why it still exists is the interesting part.
The old system still had a job
A newer version of the product had lived beside its predecessor for years. The old one still held a critical DXF export needed by long-standing customers. The team wanted to rewrite it, but had not found the resources.
So the new system grew, the old one stayed, and connections accumulated between them. From a distance, that can look like irrational architecture. Up close, it is ten years of customers, compatibility, urgent work, and constrained choices compressed into a codebase.
I could list the technical problems: old Python and PostGIS versions, monolithic components, weak CI/CD, unreliable staging, limited monitoring, scarce documentation, and no dedicated QA function. But the list still did not answer the most useful question: why couldn’t the team improve these things gradually?
I closed the IDE and talked to people
The team was small: a technical lead, several junior developers, domain specialists, and people in analysis and product roles. I sat in on daily and weekly meetings, then spoke separately with almost everyone.
Having an outsider arrive to “assess the team” can make people understandably guarded. I tried to make those calls feel like ordinary conversations between colleagues. I asked what they had worked on, what frustrated them, whether they felt they were growing, and what got in the way. I also asked the developers what they knew about that 6,800-line file.
People described the same company differently. One found tasks vague; another liked the flexibility. One struggled with the technical lead’s style; another found him fair and supportive. Documentation was inadequate to some and sufficient to others. One interview could have led me badly astray. Across independent conversations, though, a pattern kept returning.
Almost the entire system lived in one person’s head.
One person knew almost everything
Why did this module work this way? Ask the lead. How did the old integration behave? Ask the lead. Was it safe to change this part? Ask the lead. How should a new task be built in the older product? Again, ask the lead.
That was a bus factor of one: if he became unavailable, critical knowledge would disappear from the team. At the same time, he was acting as a backend developer, architect, reviewer, DevOps engineer, support contact, analyst, task writer, and manager. The more the team needed his knowledge, the less time he had to document it or teach anyone else. The older and more intimidating a module became, the more people needed him before touching it.
- Legacy raises the cost of a change.
- A change needs deep system knowledge.
- That knowledge sits with the lead.
- Every decision and review queues up with him.
- Overload leaves no time to share the knowledge.
The next change starts in the same place.
The lead was a good engineer with deep product knowledge. That was an important finding, not a contradiction. The problem was the role the company had built around him. Being an excellent engineer does not automatically mean wanting to manage people, handle conflict, coach juniors, and give delicate feedback. Under that load, communication could become sharp, and some junior developers grew afraid of making mistakes.
The juniors were not the problem either. I saw people learning, delivering work independently, writing tests, and handling backend, frontend, containers, and GIS tasks. Some showed more independence than their titles suggested. But when requirements live mostly in someone else’s head, reviews feel like exams, and the main expert is always busy, people learn to avoid mistakes rather than improve the system.
That is how technical debt becomes an organizational problem. Adding three more developers to the same approval queue would only make the queue longer.
What I recommended
I did not recommend rewriting a working ten-year-old product from scratch. The business still needed to serve its customers. I proposed changing the development system in steps.
- Separate technical leadership from people and delivery management. Keep the lead focused on architecture, difficult engineering decisions, consultation, and review of critical changes. Put task definition, priorities, coordination, and communication into another role.
- Make knowledge transfer part of technical debt work. Reserve a fixed share of development capacity for older modules, documentation, and upgrades. Have another developer work through a risky module with the person who knows it: why is it built this way, what constraints matter, and what would break? Then change a bounded part, review it, and record what they learned. The output is better code, useful documentation, and another person who understands that part of the system.
- Give the team a reliable path to ship. Improve CI/CD and staging, add a basic QA function with smoke checks, and document the architecture, data layers, important modules, and export pipelines.
- Write down the work and its direction. Use a consistent task flow, capture context in writing, and give the team a roadmap. A developer deciding between a two-day patch and a week-long solution needs to know whether that code is expected to last five years.
- Make questions and mistakes discussable. People need room to surface a risk early, ask for context, and learn from review without feeling punished for it.
None of those steps was a magic fix. Together, they could begin to break the loop.
The report was about causes, not culprits
At the end of the week I delivered a report on the technical state of the product, the team, the main risks, and a stabilization plan. The company found it useful and decided to take the recommendations forward.
The most valuable change during that week was in the question itself. “Why is development slow?” became a chain I could explain: a decade of legacy and missing engineering processes made changes costly; knowledge concentrated around one overloaded lead; juniors lacked context; reviews and decisions piled up; and there was less time to reduce the debt that had started the cycle.
“The team is not broken. It is disorganized.”
I began with a giant Python file and ended up talking about knowledge, responsibility, and the psychology of code review. That is the part of technical audits I enjoy most. Strange code can have a customer requirement behind it. A legacy module can hold the one feature an old client still needs. An exhausted lead can be a good engineer carrying seven jobs. A “slow team” can be a capable group working inside a system that makes speed difficult.
A useful audit should explain how that system got there, what keeps it in place, and what needs to change so the same audit is not necessary again a year later.